
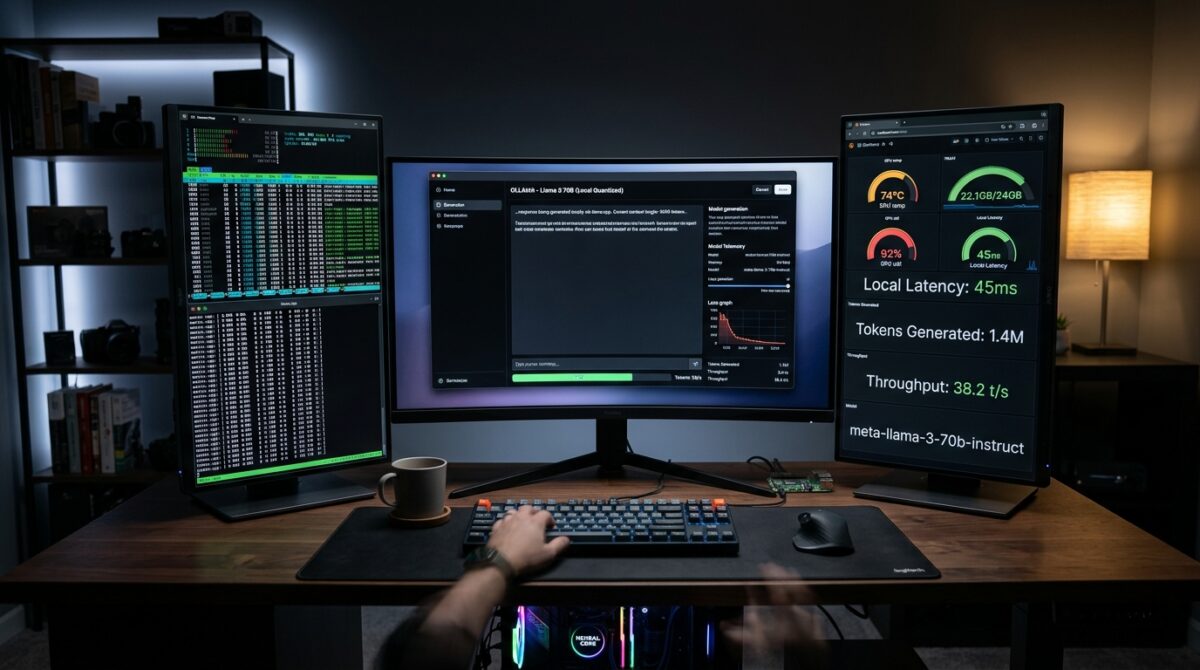
Deconstructing 2026 Production LLM Runtimes: vLLM, TensorRT-LLM, and the Memory Fragmentation Crisis
Kamal Ahmed analyzes 2026 production LLM runtimes, exposing hidden KV cache fragmentation, PagedAttention limits, and hardware utilization realities.