Deconstructing Llama-4-Maverick-70B: Why Open-Weights MoE is Breaking Quantized Inference Economics
A deep empirical dive into Llama-4-Maverick-70B. We examine FP8 tensor parallelism, decentralized fine-tuning constraints, and true memory bandwidth.

A deep empirical dive into Llama-4-Maverick-70B. We examine FP8 tensor parallelism, decentralized fine-tuning constraints, and true memory bandwidth.
Kamal Ahmed analyzes why production inference engines are abandoning Python runtimes for C++23 native architectures to slash tail latency.
Kamal Ahmed analyzes CXL 3.0 and optical interconnects in 2026, dissecting how hyperscalers bypass the PCIe bottleneck in exascale GPU clusters.
An engineering deep-dive into DeepSeek-V4’s FP8 Mixture-of-Experts architecture, exposing why legacy vLLM pipelines fail under heavy routing loads.
A hands-on breakdown of vLLM v0.7.2 deployment realities, tackling PagedAttention block allocation overheads, FP8 KV-cache drift, and cluster scaling.
Kamal Ahmed analyzes HBM4 architectures, exposing the hidden power penalties, thermal walls, and interconnect bottlenecks facing enterprise AI clusters.
A deep engineering analysis of Llama-4-Maverick’s MoE routing, cross-node communication overhead, and real-world inference realities.
A technical post-mortem of vLLM v0.8.2 and FlashAttention-3 in high-concurrency production, exposing allocation failures and KV cache bottlenecks.
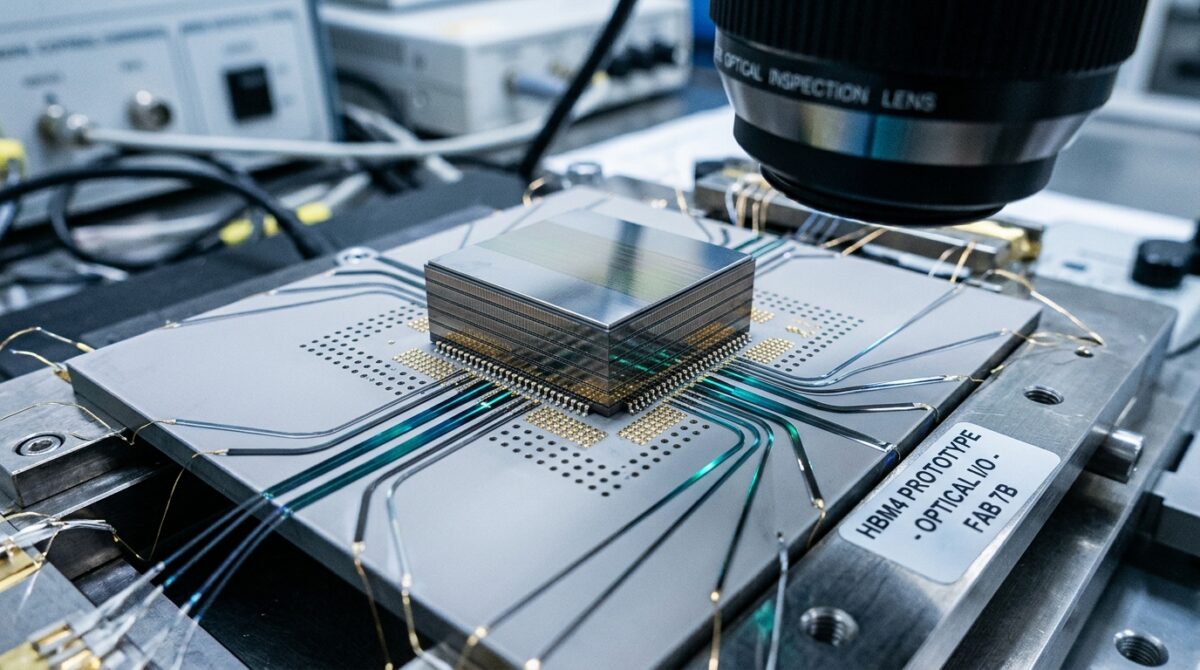
Kamal Ahmed analyzes HBM4 2048-bit interfaces, custom foundry logic dies, and the thermal bottlenecks facing 2026 AI superclusters.
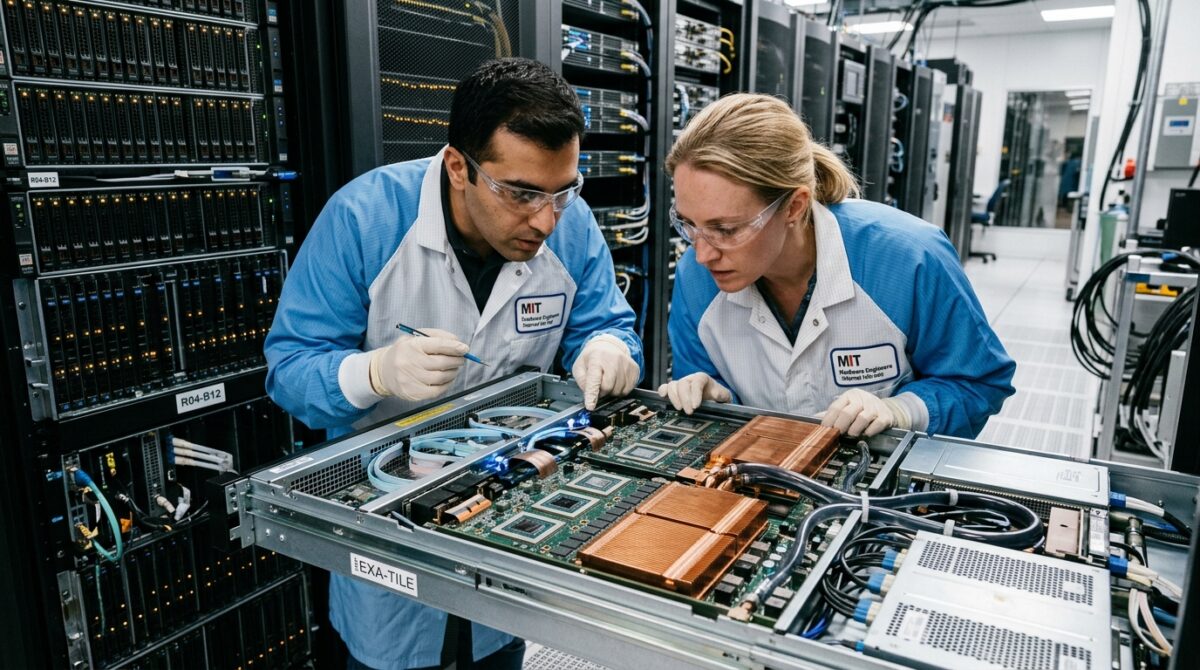
An empirical architectural analysis of DeepSeek-V4 open-weights Mixtape MoE, memory bandwidth bottlenecks, and enterprise runtime economics.