De-Escalating the Inference Tax: Why vLLM v0.8.2 and FP8 PagedAttention Are Breaking the Memory Wall
Kamal Ahmed analyzes vLLM v0.8.2, examining how FP8 PagedAttention and kernel optimizations slash memory footprints and elevate throughput.

Kamal Ahmed analyzes vLLM v0.8.2, examining how FP8 PagedAttention and kernel optimizations slash memory footprints and elevate throughput.
Kamal Ahmed analyzes HBM4 16-high stacks, foundry logic dies, and co-packaged silicon photonics. Real benchmarks, fail modes, and 2026 infra realities.
Kamal Ahmed analyzes test-time compute scaling, speculative decoding trade-offs, and why frontier reasoning architectures break traditional SLA boundaries.
An empirical deep-dive into DeepSeek-V4’s dynamic token allocation, open-weights economics, and real-world inference failure modes.
A hands-on infrastructural teardown of vLLM v0.7.2 and TensorRT-LLM 0.16. We analyze TTFT, memory fragmentation, and GPU utilization across production clusters.
Kamal Ahmed analyzes how HBM4 limits and co-packaged optics redefine high-performance AI clusters, breaking down real-world latency, thermal limits, and interconnect scaling.
An empirical analysis of DeepSeek-V4’s multi-head latent attention and routed MoE routing, exposing true inference costs and memory footprints for CTOs.
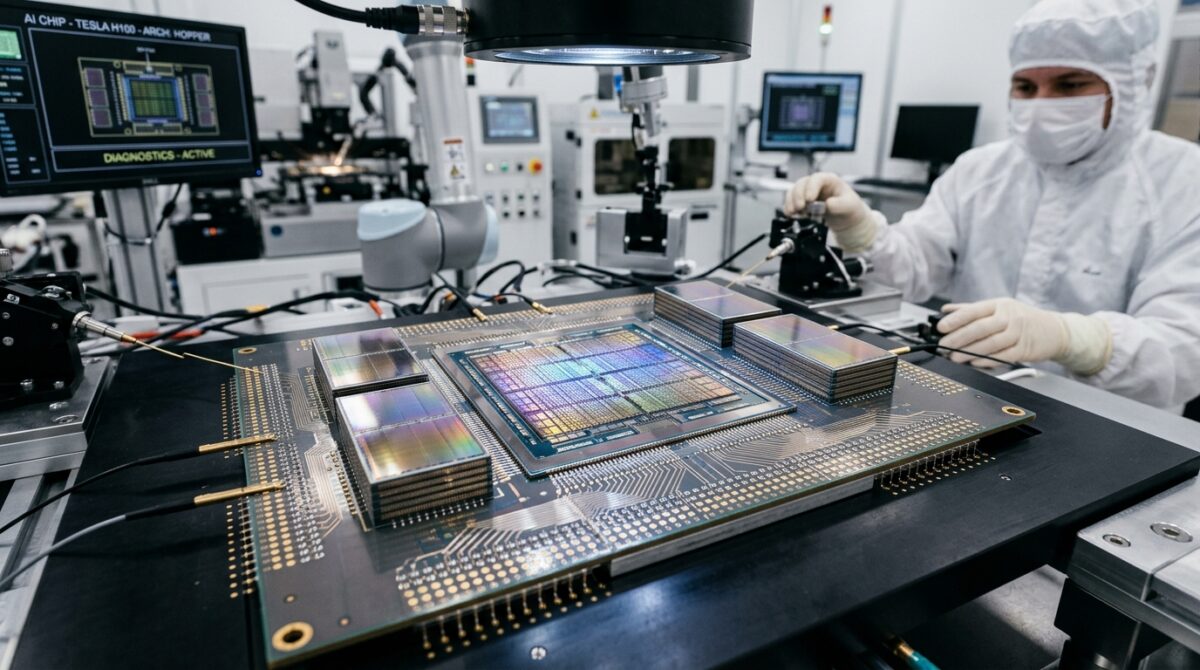
Kamal Ahmed analyzes how Triton-native inference engines displace legacy runtimes, cutting GPU memory overhead and boosting token throughput in production.
Kamal Ahmed investigates HBM4, optical interconnects, and ASIC accelerators, analyzing real-world memory bandwidth limits and production failure modes.
A deep dive into Llama-4-Maverick’s mixture-of-experts architecture, uncovering decentralized fine-tuning telemetry, memory overhead, and production bottlenecks.