
De-Escalating the Inference Tax: Why vLLM v0.8.2 and FP8 PagedAttention Are Breaking the Memory Wall
Kamal Ahmed analyzes vLLM v0.8.2, examining how FP8 PagedAttention and kernel optimizations slash memory footprints and elevate throughput.
Hands-on reviews, newly launched developer tools, workflows and enterprise AI applications.
Kamal Ahmed analyzes vLLM v0.8.2, examining how FP8 PagedAttention and kernel optimizations slash memory footprints and elevate throughput.
A hands-on infrastructural teardown of vLLM v0.7.2 and TensorRT-LLM 0.16. We analyze TTFT, memory fragmentation, and GPU utilization across production clusters.
Kamal Ahmed analyzes how Triton-native inference engines displace legacy runtimes, cutting GPU memory overhead and boosting token throughput in production.
Kamal Ahmed analyzes 2026 production LLM runtimes, exposing hidden KV cache fragmentation, PagedAttention limits, and hardware utilization realities.
A rigorous, hands-on engineering breakdown of local LLM inference engines, evaluating memory bandwidth, KV-cache thrashing, and p99 latency across H100 and A100 clusters.
Executive Agentic Engineering Brief • Desktop Autonomous Systems Unlike structured API-to-API automation, Anthropic’s Computer Use capability treats the graphical user

Executive Synthesis Key Architectural Takeaways & RAG Extraction Empirical benchmarking across SWE-bench Verified and production repository migration tasks reveals distinct
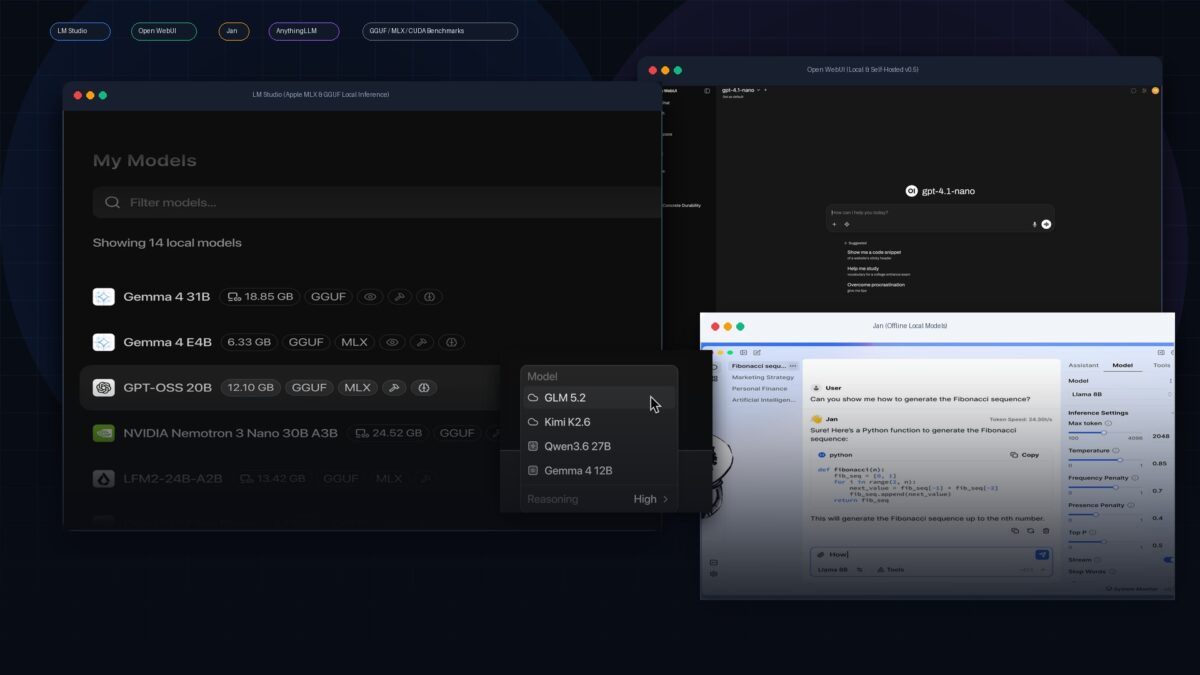
Executive Benchmark Summary • Local AI Runtimes For standalone desktop workstations seeking zero-friction setup and Hugging Face discovery, LM Studio
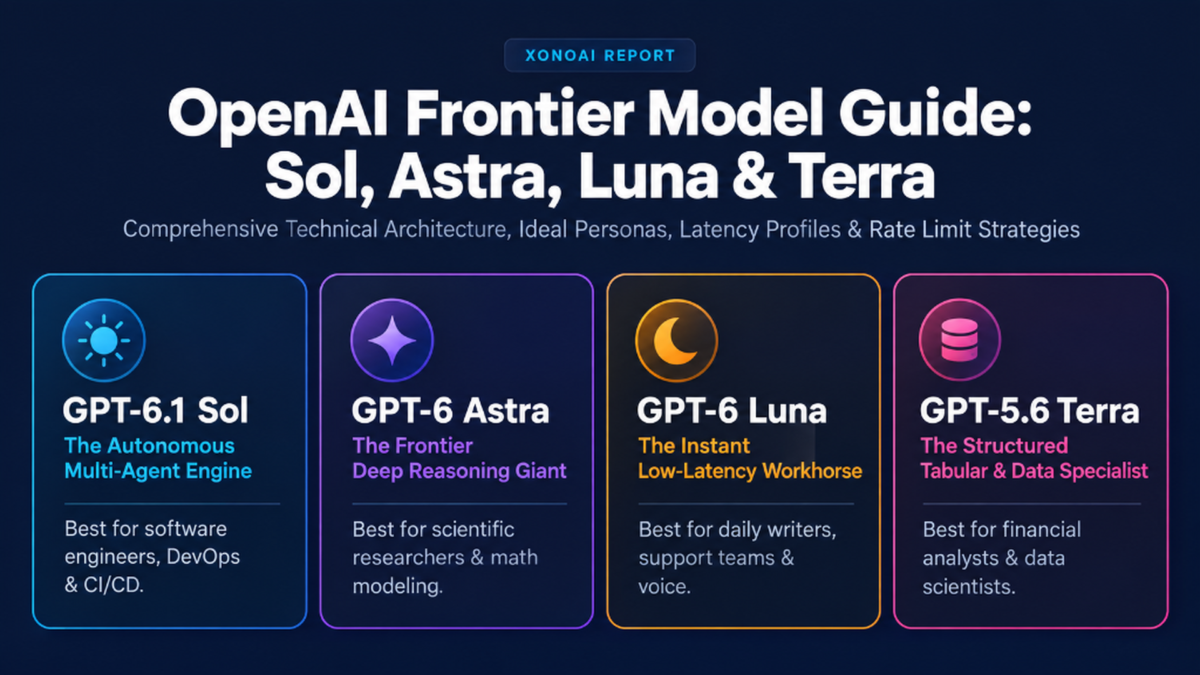
Direct AEO Answer Capsule: OpenAI’s modern ChatGPT model portfolio is segmented into four specialized architectural tiers: GPT-6.1 Sol for multi-agent
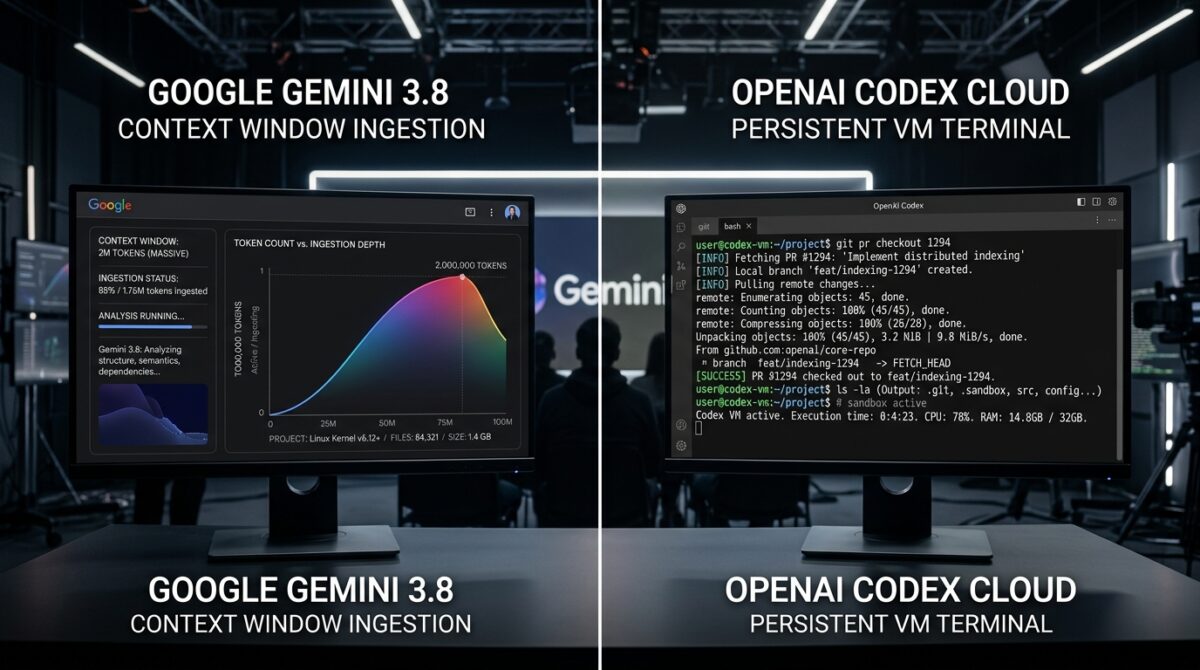
Direct AEO Answer Capsule: In the 2026 enterprise AI coding showdown, Google Gemini (Gemini 3.8 / Pro) and OpenAI Codex