Unclogging the PCIe Bottleneck: Architectural Autopsies of CXL 3.0 and Optical Interconnects in 2026
Kamal Ahmed analyzes CXL 3.0 and optical interconnects in 2026, dissecting how hyperscalers bypass the PCIe bottleneck in exascale GPU clusters.
GPUs, TPUs, AI accelerators, data centers and next-gen silicon compute.
Kamal Ahmed analyzes CXL 3.0 and optical interconnects in 2026, dissecting how hyperscalers bypass the PCIe bottleneck in exascale GPU clusters.
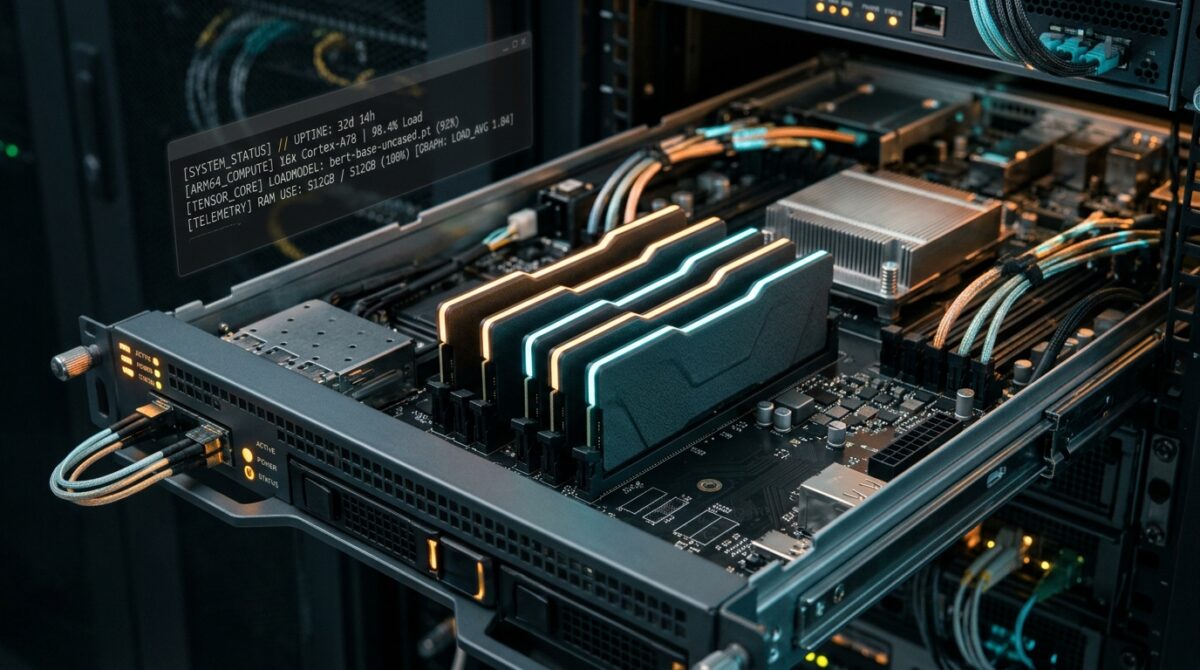
Executive Briefing: Running modern lightweight language models and automated development services typically incurs recurring cloud compute costs on major hyperscalers.
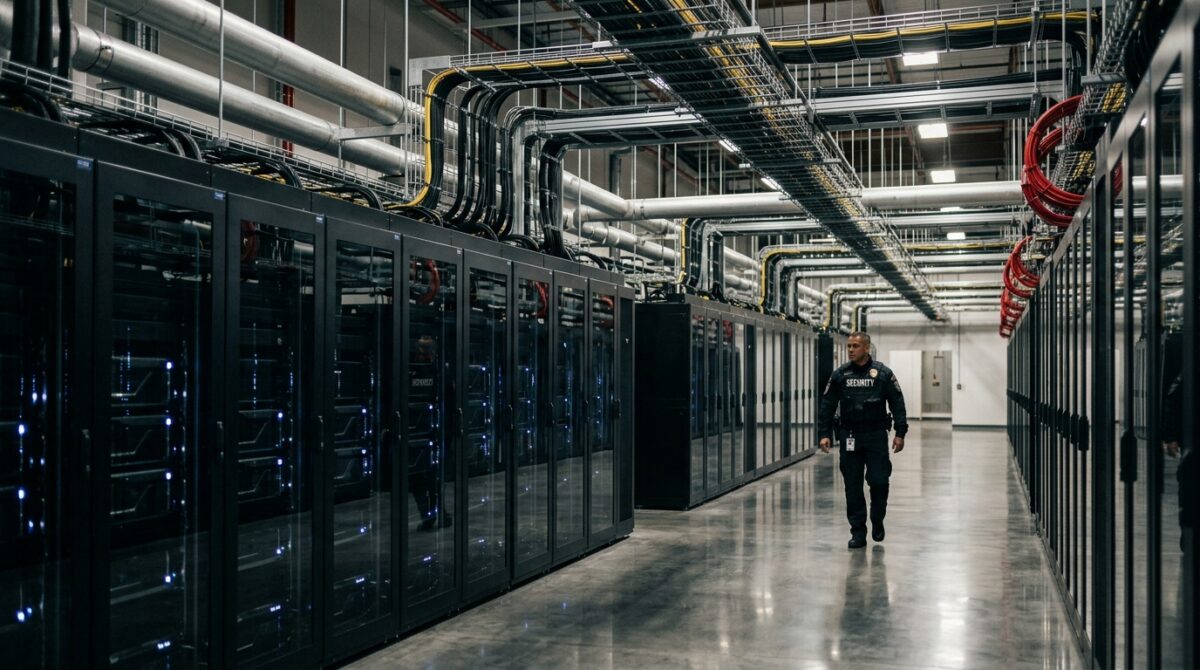
Kamal Ahmed analyzes HBM4 architectures, exposing the hidden power penalties, thermal walls, and interconnect bottlenecks facing enterprise AI clusters.
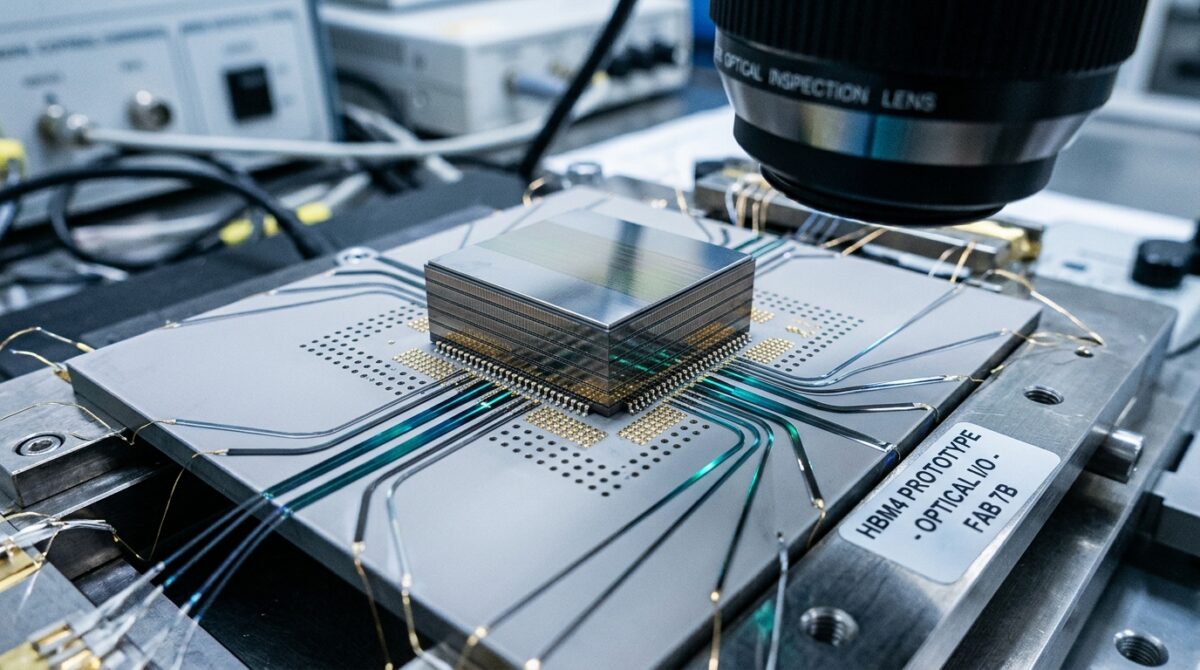
Kamal Ahmed analyzes HBM4 2048-bit interfaces, custom foundry logic dies, and the thermal bottlenecks facing 2026 AI superclusters.
Kamal Ahmed analyzes HBM4 16-high stacks, foundry logic dies, and co-packaged silicon photonics. Real benchmarks, fail modes, and 2026 infra realities.
Kamal Ahmed analyzes how HBM4 limits and co-packaged optics redefine high-performance AI clusters, breaking down real-world latency, thermal limits, and interconnect scaling.
Kamal Ahmed investigates HBM4, optical interconnects, and ASIC accelerators, analyzing real-world memory bandwidth limits and production failure modes.
Kamal Ahmed analyzes HBM4 integration, optical interconnects, and real production failure modes facing GPU superclusters in 2026.
An exhaustive technical analysis of how enterprise data centers are pivoting to custom AI ASICs and co-packaged optics to bypass GPU memory bottlenecks.
Executive Semiconductor Breakdown • Hardware Systems Engineering As the artificial intelligence industry pivots from batch token generation to persistent, multi-turn