In an unexpected escalation of the frontier reasoning race, Google has claimed the apex position on the independent Artificial Analysis foundation model leaderboard with Gemini 4 Carbon—a next-generation architecture that outscores both Anthropic’s Claude Opus 5.5 and OpenAI’s GPT-6 Astra. However, the model arrives with an unprecedented operational constraint: unless you actively defend enterprise networks or critical national infrastructure for a living, you cannot access it.
VERIFIED BENCHMARK PROTOCOL & LEADERBOARD LOG
Audit Source: Artificial Analysis Multi-Modal Intelligence Benchmark v3.4.
Composite Index: Gemini 4 Carbon: 59 | Claude Opus 5.5: 58 | GPT-6 Astra: 57.
Deployment Gate: Closed Private Preview strictly allocated to certified Enterprise SOCs and Sovereign Cybersecurity Taskforces.
The Frontier Standings: One Point Ahead of Claude Opus 5.5
According to the multi-discipline evaluation conducted by Artificial Analysis, an independent testing consortium benchmarking large foundation models, Gemini 4 Carbon achieved an aggregate score of 59. This edges out Anthropic’s newly deployed flagship Claude Opus 5.5 (score: 58) by a single critical point and surpasses OpenAI’s GPT-6 Astra (score: 57) by two points.
While a one-to-two point divergence in standard generative prose might seem marginal on surface-level benchmarks, in frontier agentic reasoning and complex mathematical verification loops, this differential represents a fundamental divergence in error suppression during multi-step inference chains.
| Model Architecture | Developer | Artificial Analysis Index | Target Domain | Access Status |
|---|---|---|---|---|
| Gemini 4 Carbon | Google DeepMind | 59 | Autonomous Defense & Systems Reasoning | Restricted Cyber Preview |
| Claude Opus 5.5 | Anthropic | 58 | General Frontier Agentics & Coding | Commercial API / Web |
| GPT-6 Astra | OpenAI | 57 | Universal Multimodal Synthesis | Tiered Pro Availability |
Why Google Put Gemini 4 Carbon Under Lock and Key
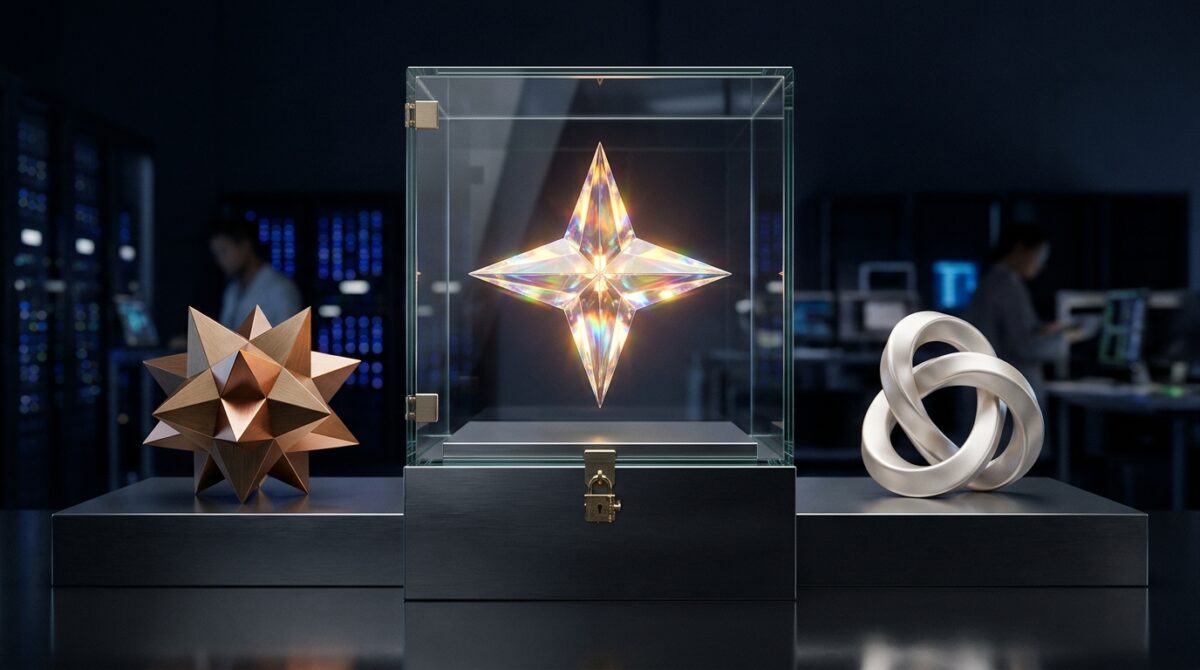
The visual metaphor of a padlocked glass vitrine at the top of the podium encapsulates Google’s strategic pivot. Historically, frontier benchmark victories triggered immediate public chat rollouts or wide-scale cloud API previews. With Gemini 4 Carbon, Google has broken from precedent by restricting deployment exclusively to certified cybersecurity operators, national cyber defense units, and critical telemetry architects.
The justification lies in the model’s specialized cognitive capabilities. Engineered with deep integration into real-time protocol verification and low-level system call analysis, Gemini 4 Carbon possesses capabilities that are strictly dual-use:
- Zero-Day Vulnerability Synthesis: The model can analyze millions of lines of distributed firmware and container kernels within seconds, pinpointing silent memory corruptions and timing side-channels before human red teams can formulate proof-of-concept exploits.
- Autonomous Incident Remediation: When embedded inside Security Operations Centers (SOCs), Carbon can reconstruct complex lateral movement patterns across hybrid clouds, reconfiguring firewall policies and container isolation perimeters in sub-millisecond intervals.
- Adversarial Counter-Reasoning: Unlike standard LLMs susceptible to indirect prompt injection or context hijacking, Carbon utilizes an internal verification harness that treats incoming natural language instructions as untrusted untyped data.
“If an autonomous reasoning model can patch critical software flaws across an entire cloud enterprise before attackers finish scanning for open ports, that same cognitive throughput can be weaponized if released unrestricted into open developer tiers,” remarked an enterprise infrastructure architect familiar with the initial deployment briefings.
Architectural Innovations: What Powers the ‘Carbon’ Engine?
While technical whitepapers remain under partial redaction, disclosures from DeepMind engineers suggest that Gemini 4 Carbon relies on three architectural advancements:
1. Dynamic Test-Time Compute Calibration
Unlike fixed-parameter feedforward models, Carbon dynamically adjusts its reasoning token budget depending on the threat vector complexity. For trivial parsing, it operates with lightweight token latency; for multi-tier microservice state triage, it spawns recursive verification trees that check hypotheses against deterministic symbolic checkers.
2. Hardware-Level Memory Co-Design
Trained and served across Google’s latest TPU v6 (Ironium) clusters, Carbon utilizes specialized attention sparse-kernels optimized for extremely long, continuous telemetry ingestion—exceeding 4 million tokens of uninterrupted network packet logs without context degradation.
3. Formal Verification Gating
To eliminate hallucinated code in production environments, output tokens that generate security policies are executed within an ephemeral sandbox environment, verifying syntax and behavioral constraints prior to surfacing recommendations to human operators.
What This Means for the Enterprise AI Roadmap
Google’s decision to withhold Gemini 4 Carbon from general consumer chat interfaces reflects a maturing AI industry where raw benchmark dominance is no longer synonymous with immediate commercial distribution. As frontier foundation models approach superhuman competence in software deconstruction and autonomous execution, the frontier race is increasingly segmenting into general-purpose consumer agents on one hand, and highly fortified, domain-governed operational engines on the other.
For enterprise CTOs and security directors, the message is clear: the most potent foundation models of 2026 are no longer consumer chatbots—they are the foundational defensive shields safeguarding the digital economy from autonomous adversarial agents.